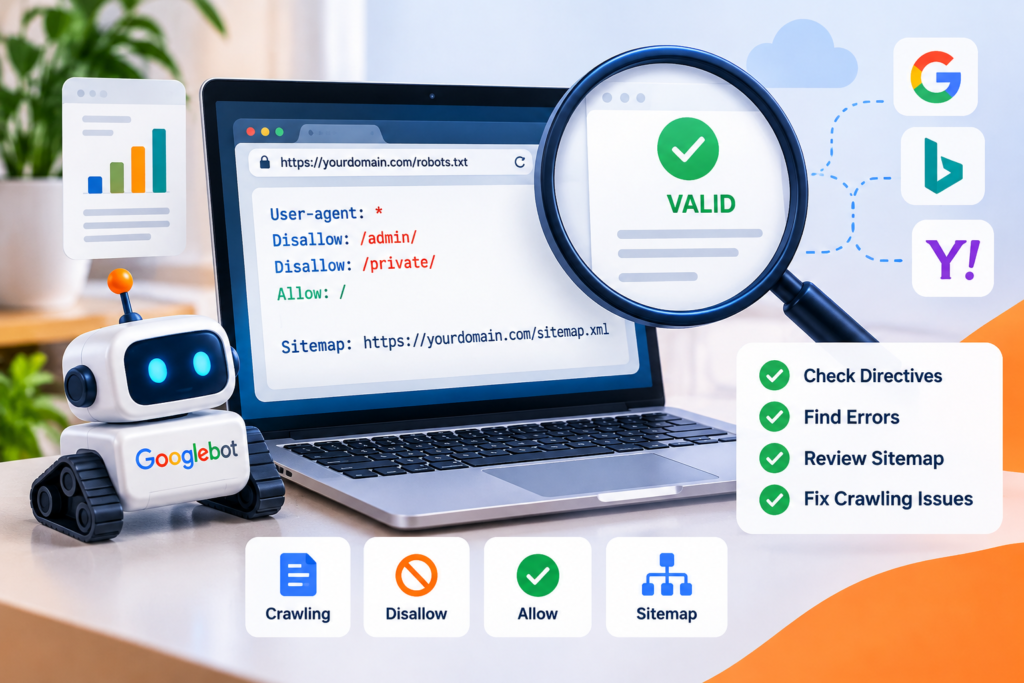
Robots.txt Validator tools help website owners check whether their robots.txt file contains crawling rules or configuration issues that could affect search engines. Before publishing or making major SEO changes, reviewing these directives can help ensure that important pages and resources remain accessible to search-engine crawlers.
A robots.txt file may look simple, but an incorrect rule can unintentionally restrict search-engine crawlers from accessing important sections of a website. That is why reviewing the file should be part of a basic technical SEO audit.
What Is a Robots.txt File?
A robots.txt file is normally located in the root directory of a website. For example:
https://example.com/robots.txt
It contains instructions that tell supported web crawlers which areas of a website they are allowed or disallowed from crawling.
A basic file might contain:
User-agent: *Disallow: /private/
In this example, the rule asks crawlers covered by the User-agent directive not to crawl the /private/ directory.
Why Robots.txt Errors Matter
Problems often occur when website owners copy rules from another website, make changes during development, or move a staging website into production without reviewing the existing configuration.
A restrictive rule could prevent crawlers from accessing content that the website owner actually wants discovered.
For example:
User-agent: *Disallow: /
The / rule can block crawling across the site for crawlers that obey it. A configuration like this may be useful temporarily in certain development environments, but it can become a serious problem if accidentally left on a public website.
Validate the File Instead of Guessing
Reading a small robots.txt file manually is easy, but larger configurations may contain several user-agent groups, allow/disallow directives, sitemap references, and path rules.
Using a Robots.txt Validator can make the review easier by helping website owners inspect their robots.txt configuration and identify potential problems before they affect crawling.
This is particularly useful after a website migration, redesign, domain change, SEO configuration update, or launch from a staging environment.
Backlink yahin lagana hai: Robots.txt Validator → https://meetmumtaz.com/robots-txt-validator/
Check Important Directives
When reviewing a robots.txt file, pay attention to User-agent, Disallow, and Allow directives.
Also check whether the file references the correct XML sitemap where appropriate. A sitemap reference commonly looks like:
Sitemap: https://example.com/sitemap.xml
Make sure old staging URLs, outdated domains, or incorrect sitemap locations have not been left behind.
Robots.txt Is Not the Same as Noindex
Another common technical SEO mistake is treating robots.txt and noindex as interchangeable.
They serve different purposes. Robots.txt primarily manages crawler access, while a noindex directive instructs compatible search engines not to include a page in their index after they can process that directive.
Because these mechanisms work differently, website owners should review both crawling and indexing signals when diagnosing search visibility problems.
Review Robots.txt After Major Website Changes
A robots.txt check is especially worthwhile after migrating a website, changing URL structures, installing or changing an SEO plugin, moving from staging to production, or modifying crawl settings.
You should also review the file periodically even when no obvious problem exists. Technical settings can change over time as websites evolve.
Final Thoughts
Robots.txt is a small file with an important role in technical SEO. A simple configuration mistake can influence how search-engine crawlers interact with a website.
Before making major SEO changes—or after launching a redesigned website—review the robots.txt file, confirm important resources are accessible, check sitemap references, and validate the directives being served.
A few minutes of checking can prevent a small configuration error from turning into a much larger crawling problem.